From documents to decisions.
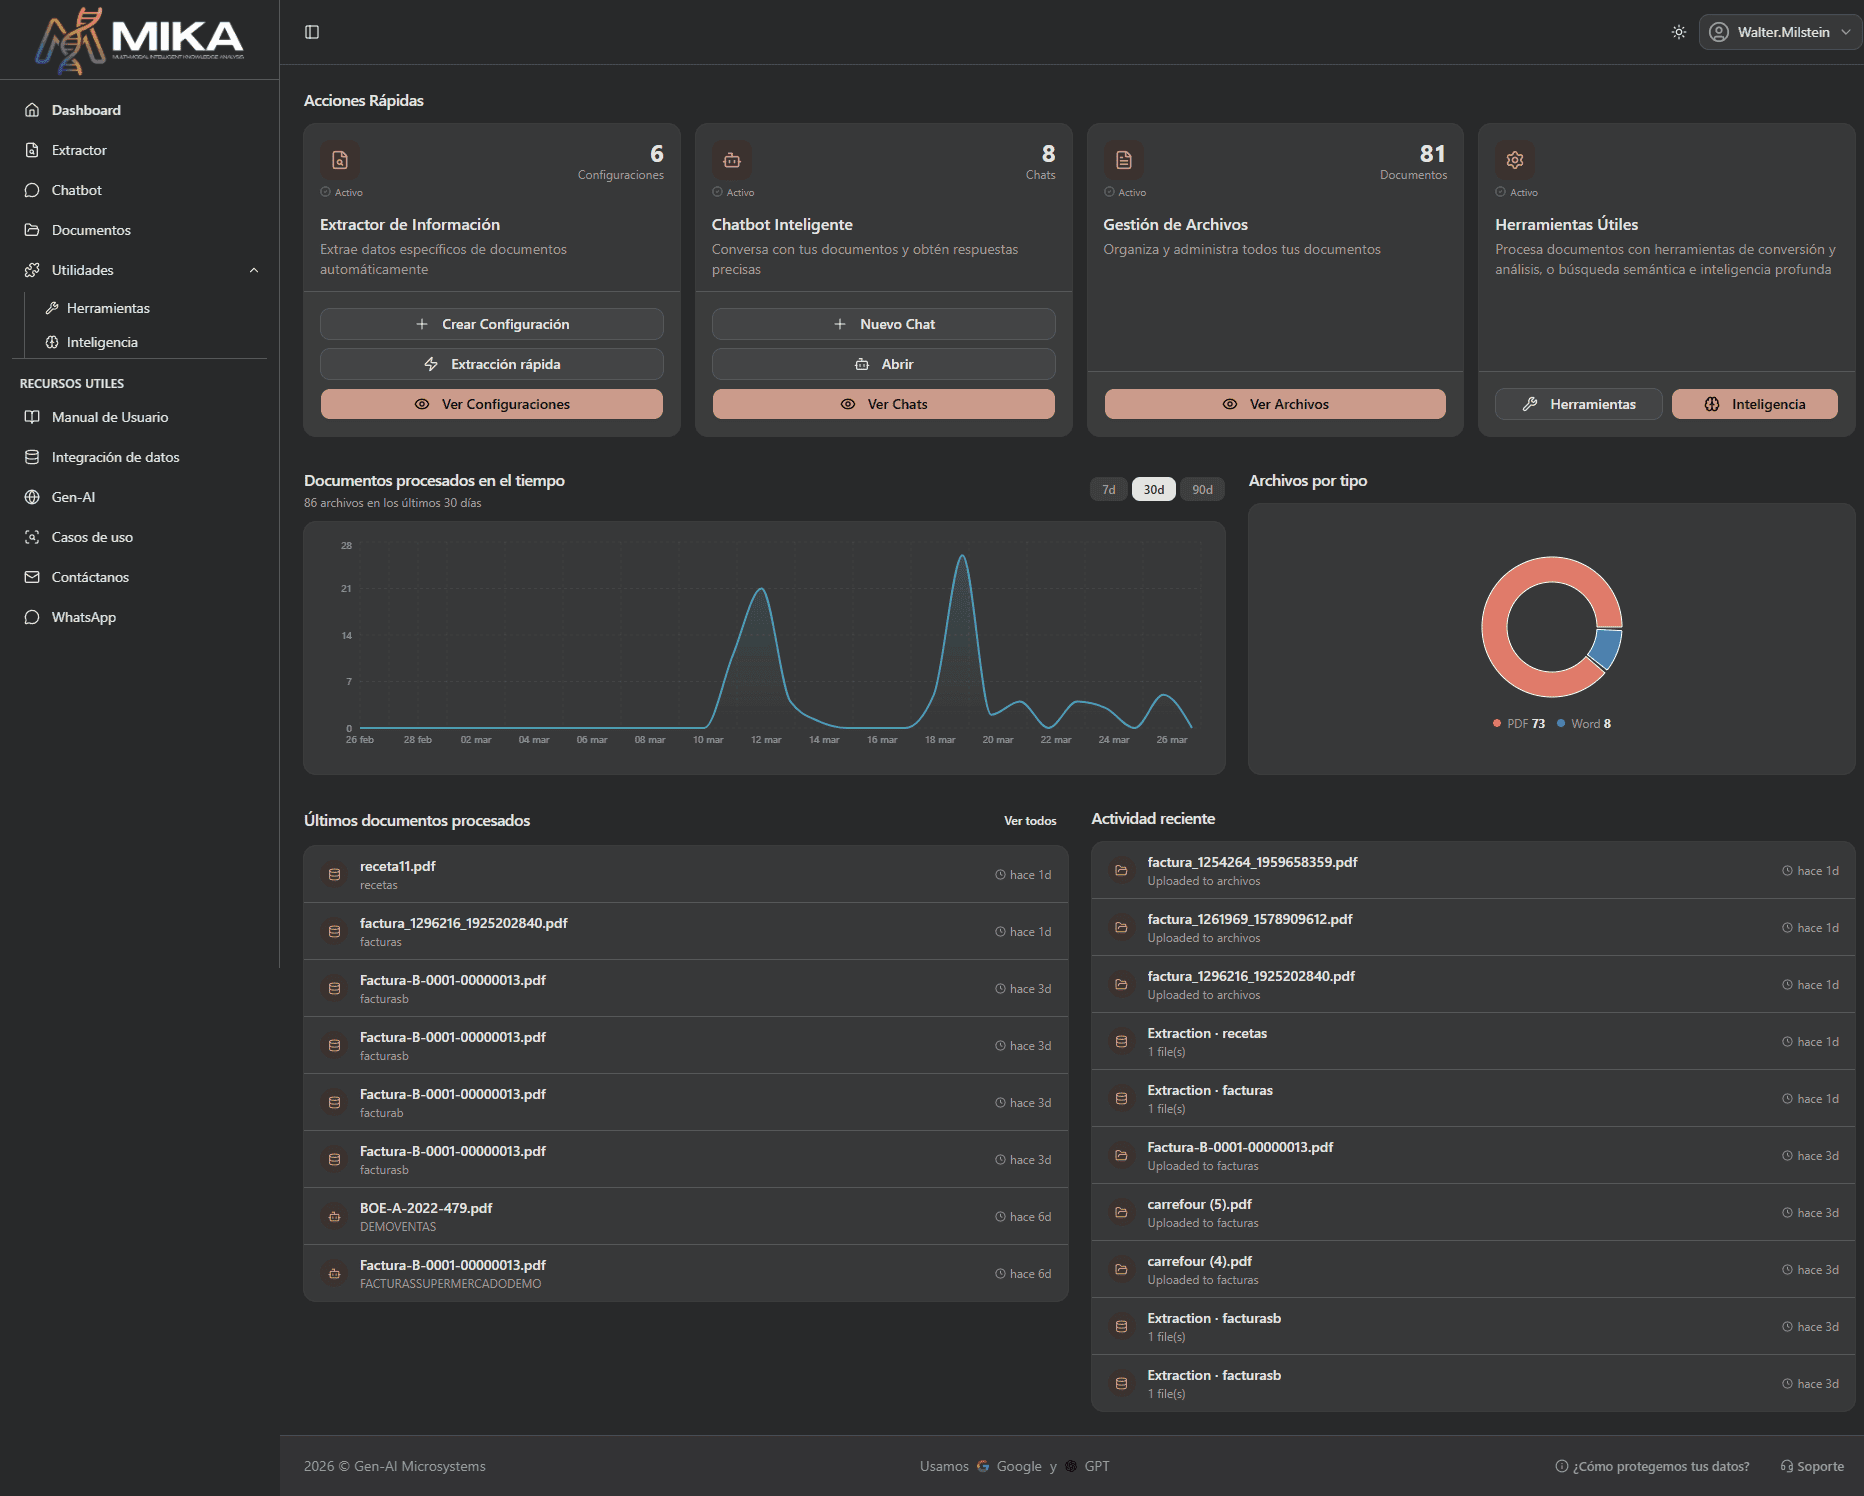
MIKA extracts, understands and organizes information from your documents by combining generative AI, traditional machine learning and Big Data in a single platform — built for industries where information carries weight: Healthcare, Insurance, Legal, Banking and Finance.
Your company's information is where you can't use it.
Without MIKA
- Teams lose hours every week searching for information inside documents.
- Auditing hundreds of contracts by hand takes several people and several weeks.
- Handwritten documents get processed manually, with errors.
- Information lives in silos: nobody finds what they need in time.
- Using public generative AI with sensitive data is a risk nobody wants to take.
With MIKA
- Semantic search: find any document by describing what you're looking for, not matching exact words.
- Audit hundreds of contracts with a fraction of the team and the time.
- Handwriting OCR: reads handwriting other systems reject.
- Automatic pseudonymization: use generative AI on sensitive data without exposing it.
- Everything connected — documents, databases and tools — in one place.
The result: less manual work, more speed, more control over your information.
Three layers of intelligence, one platform.
Most tools solve a single piece of the document problem: one extracts data, another lets you chat, another scales. MIKA integrates the three layers needed to go from document to decision without leaving the platform.
From documents to decisions. Extract with generative AI, analyze with machine learning, scale with Big Data.
Generative AI
Language models to understand, converse with and extract information from your documents.
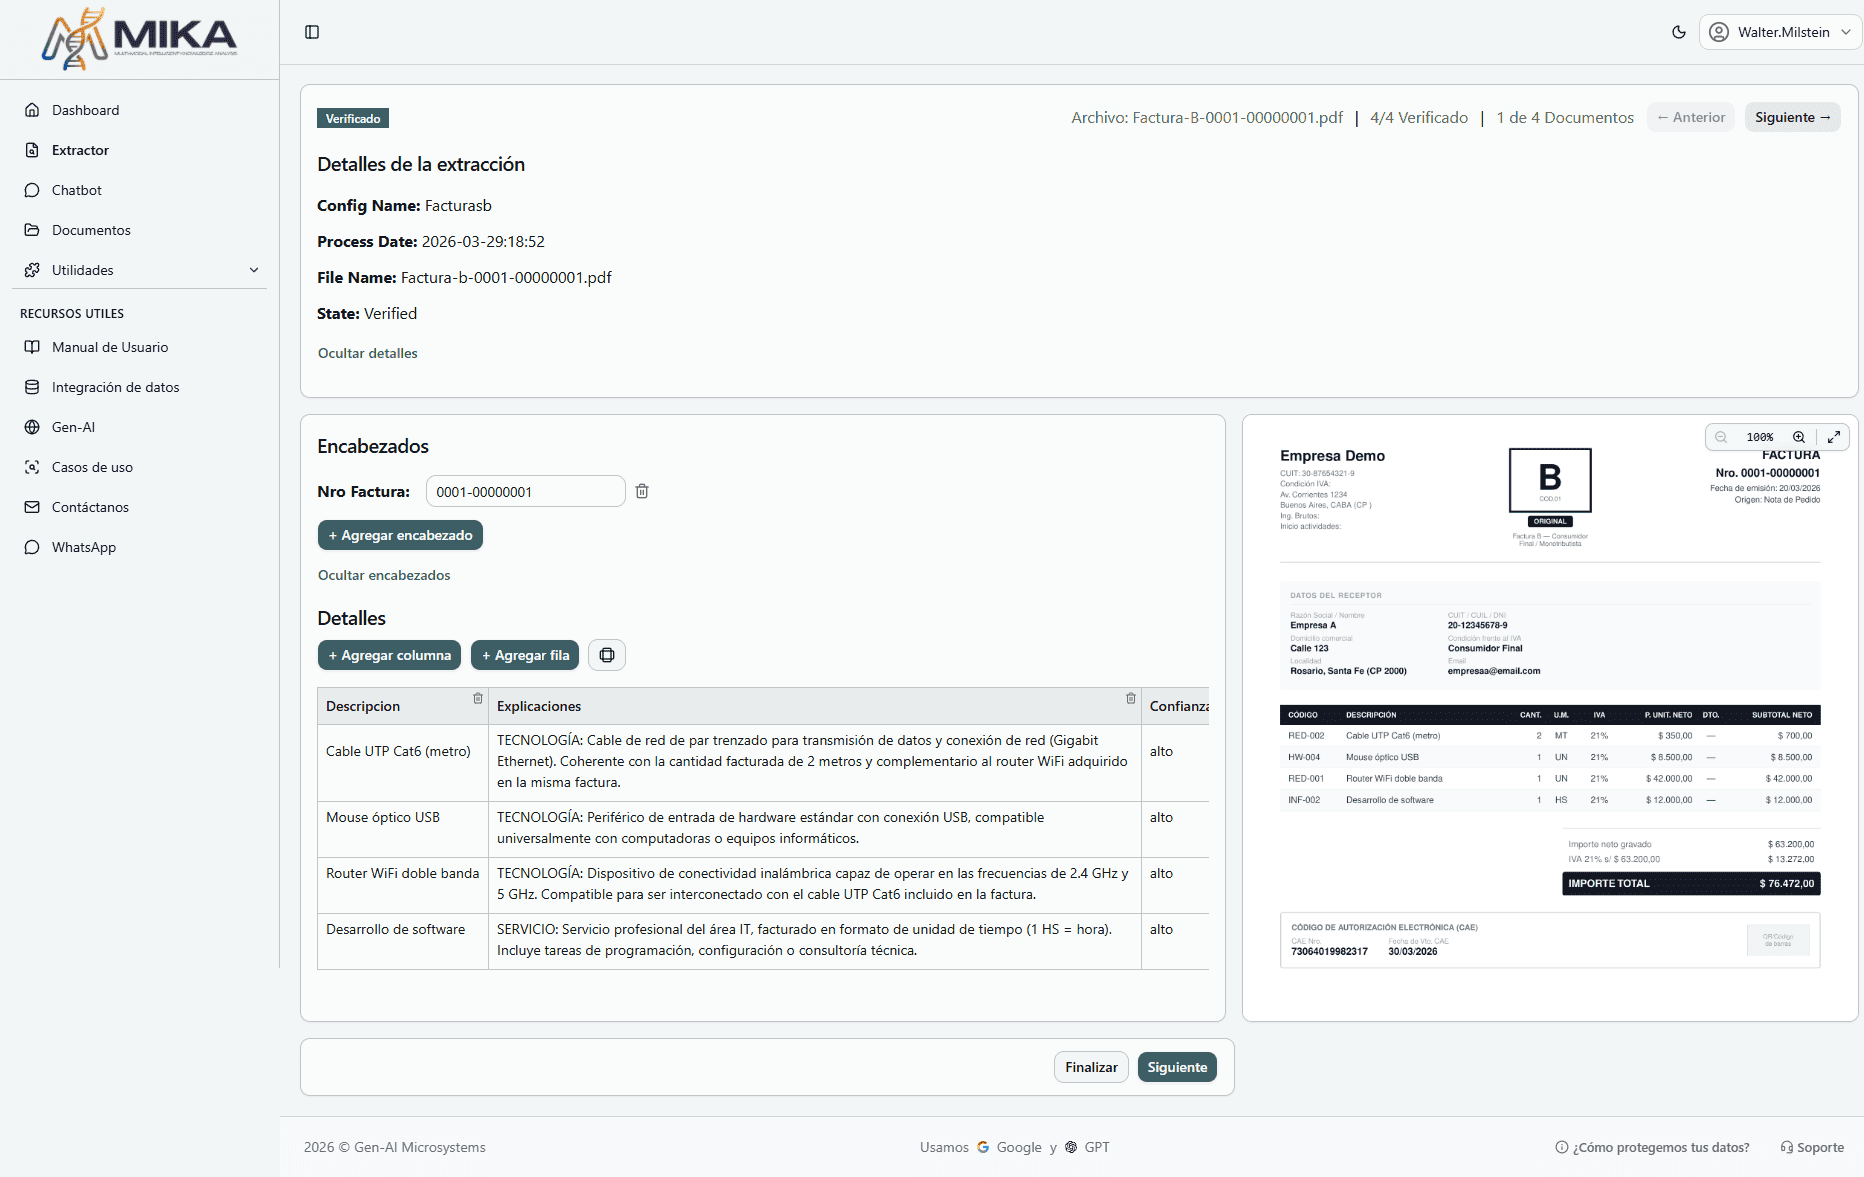
- Intelligent data extraction (invoices, contracts, forms)
- Document chat (RAG): ask in natural language, get cited answers
- OCR, including handwriting
- Multi-LLM: GPT, Gemini, Claude or MIKA's own LLM
- Automatic pseudonymization before any model sees the data
- Support in 80 languages and dialects
"What does this contract say?"
Traditional Machine Learning
Specialized models to predict, classify, detect anomalies and make decisions on your data — faster and more explainable than an LLM for this kind of task.
- Automatic document classification
- Fraud and anomaly detection
- Numeric prediction (scoring, forecasting)
- Clustering to find patterns
- Time-series models
- A catalog of 20+ models, chosen per case
"Is this document fraudulent?"
Big Data
For when volume stops being manageable with manual processes. MIKA can integrate with the large-scale data tools your company already uses.
- Distributed processing (Spark, Databricks, Hadoop)
- Data streaming (Kafka)
- Storage and orchestration at scale (Delta Lake, Airflow)
- Batch processing of millions of documents
Processes millions of documents
What you can do with MIKA every day.
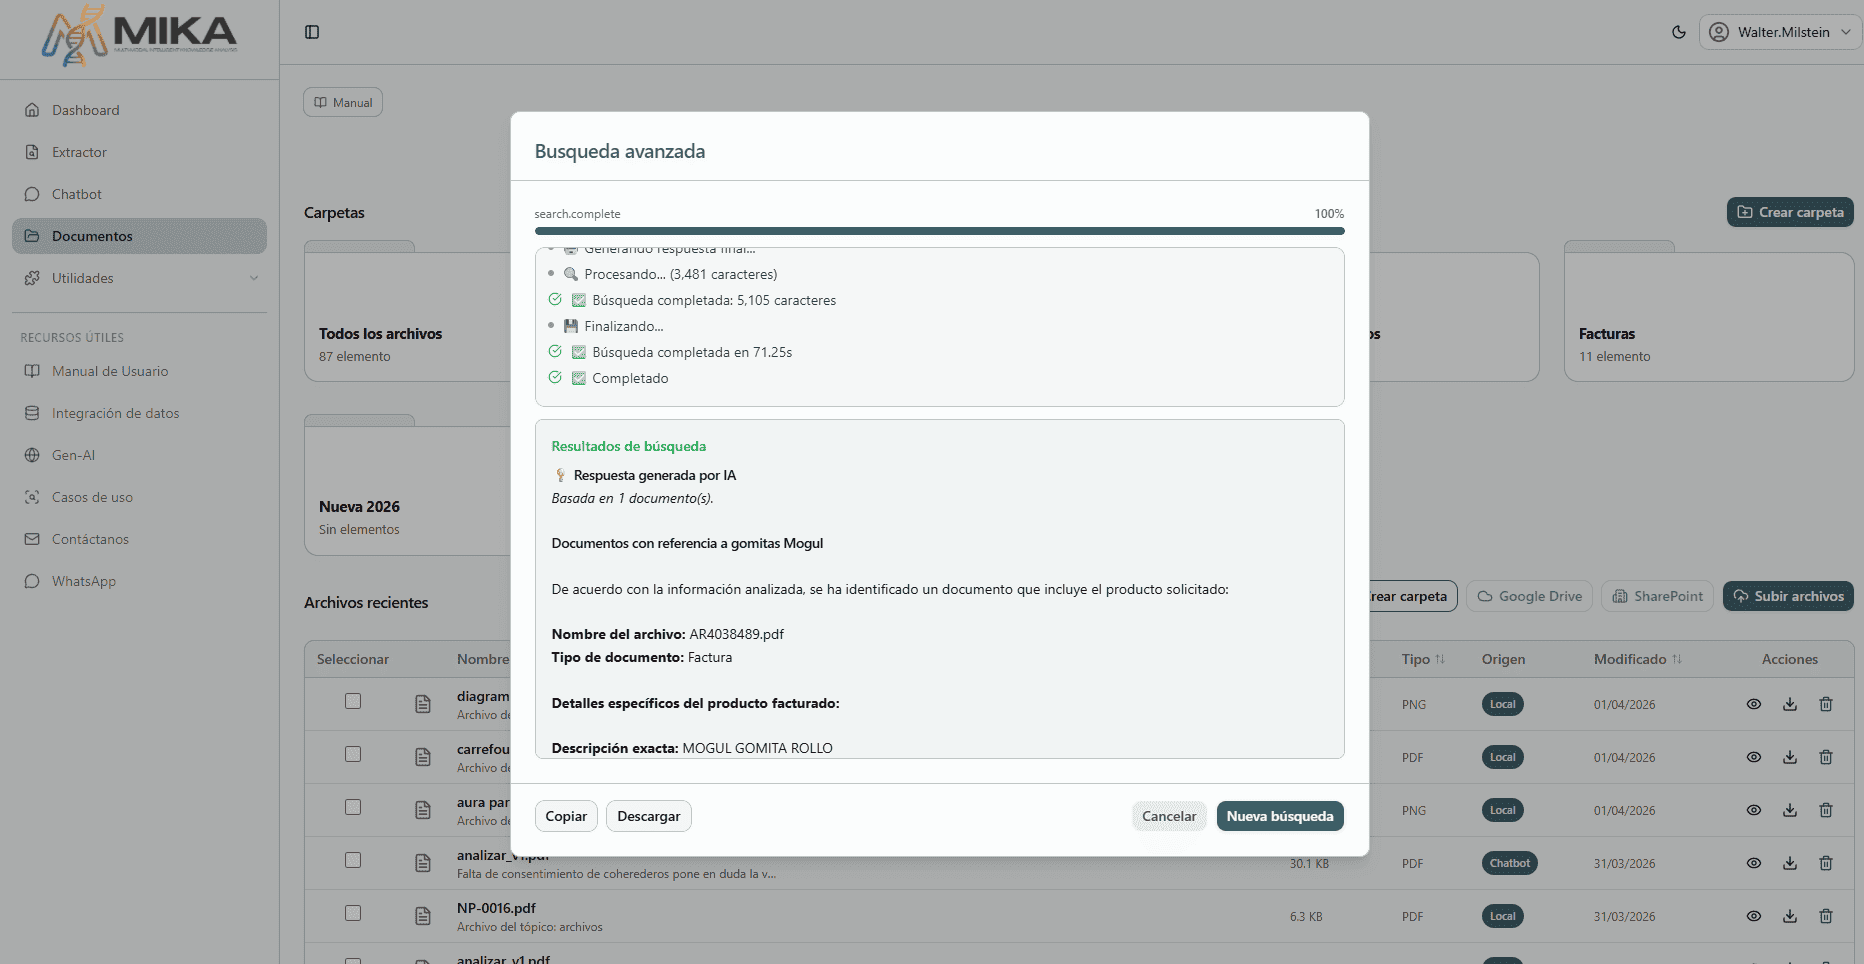
Find any document just by describing it
Forget folders and filters. Write what you need in natural language and MIKA locates the exact document among thousands, in seconds.
- Natural language — Write the way you speak: "John's contract from last year" and MIKA finds it.
- Semantic search — It doesn't match exact words — it understands the meaning and context of your query.
- Automatic filters — MIKA detects dates, document types and people from your own prompt.
- Explained results — Ranks and presents the most relevant documents with a summary of why they match.
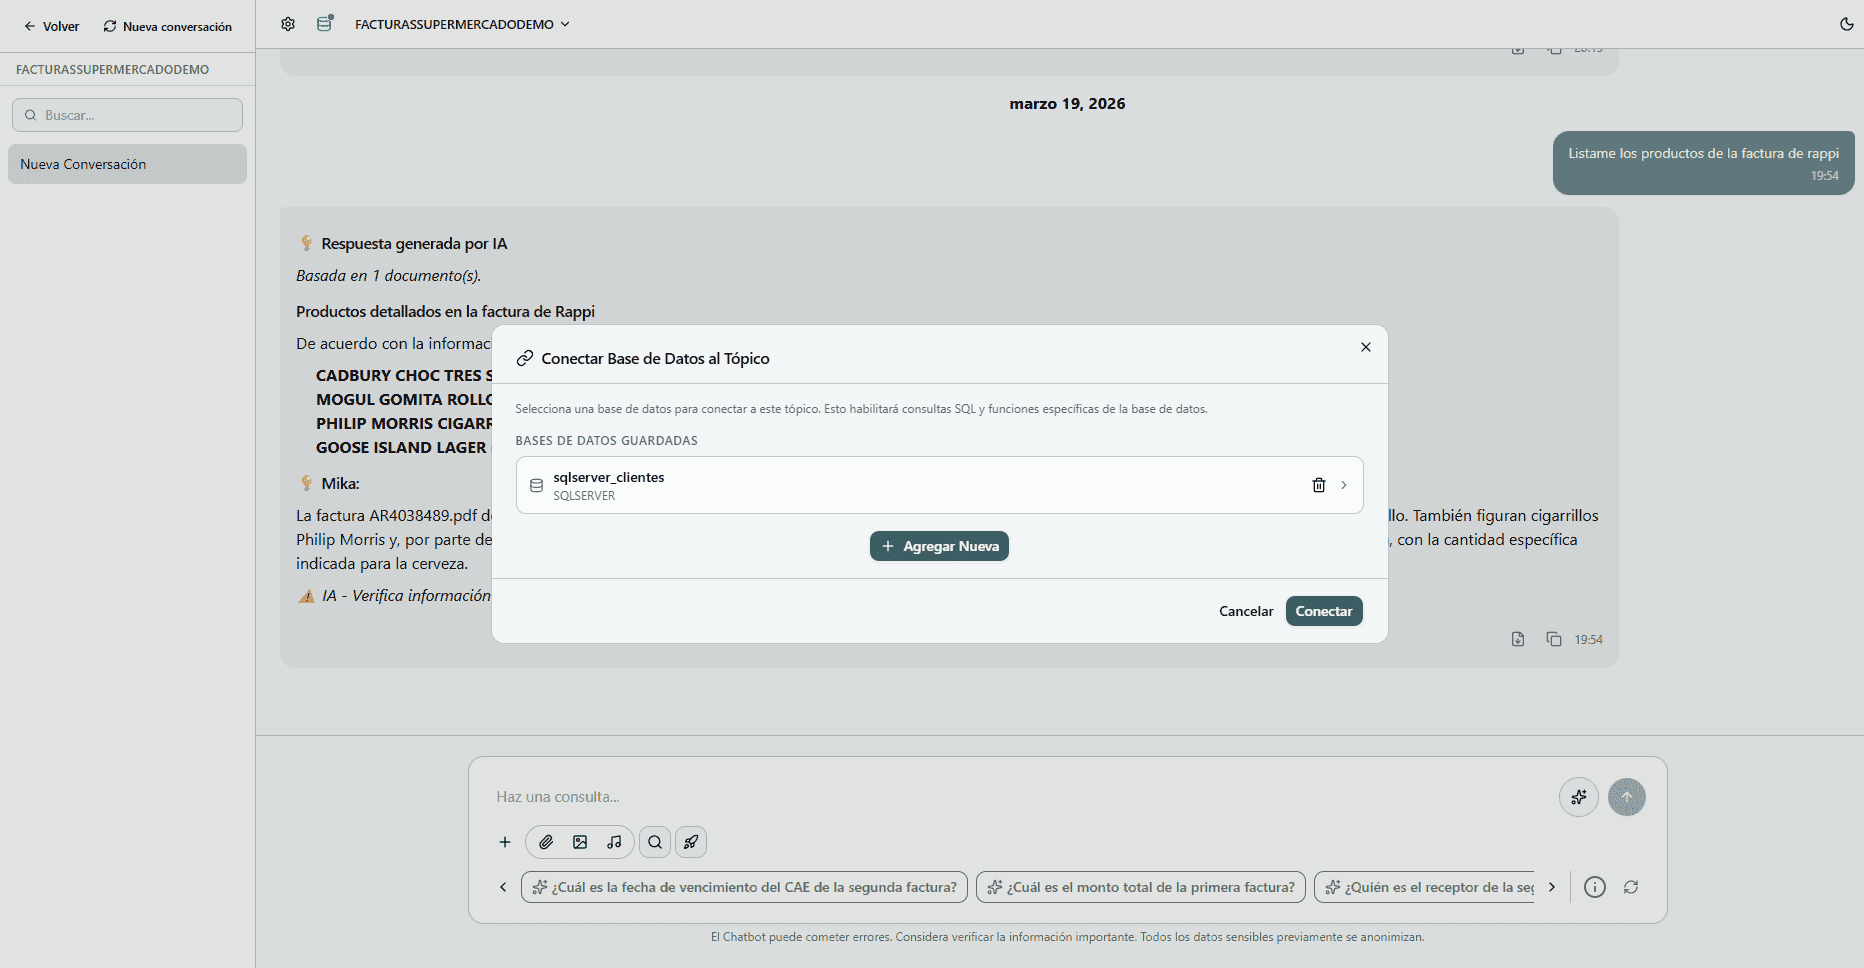
Talk to your databases
MIKA integrates with your relational and non-relational databases, so you can query structured information using the same natural language you use with your documents.
- Chat over your data — Query tables, reports and metrics in natural language, without writing SQL.
- Extractions into your database — Automatically save data extracted from documents directly into your tables.
- Enriched context — Combine documents and structured information in the same conversation.
- Ready-made connectors — Compatible with PostgreSQL, MySQL, SQL Server, MongoDB and more.
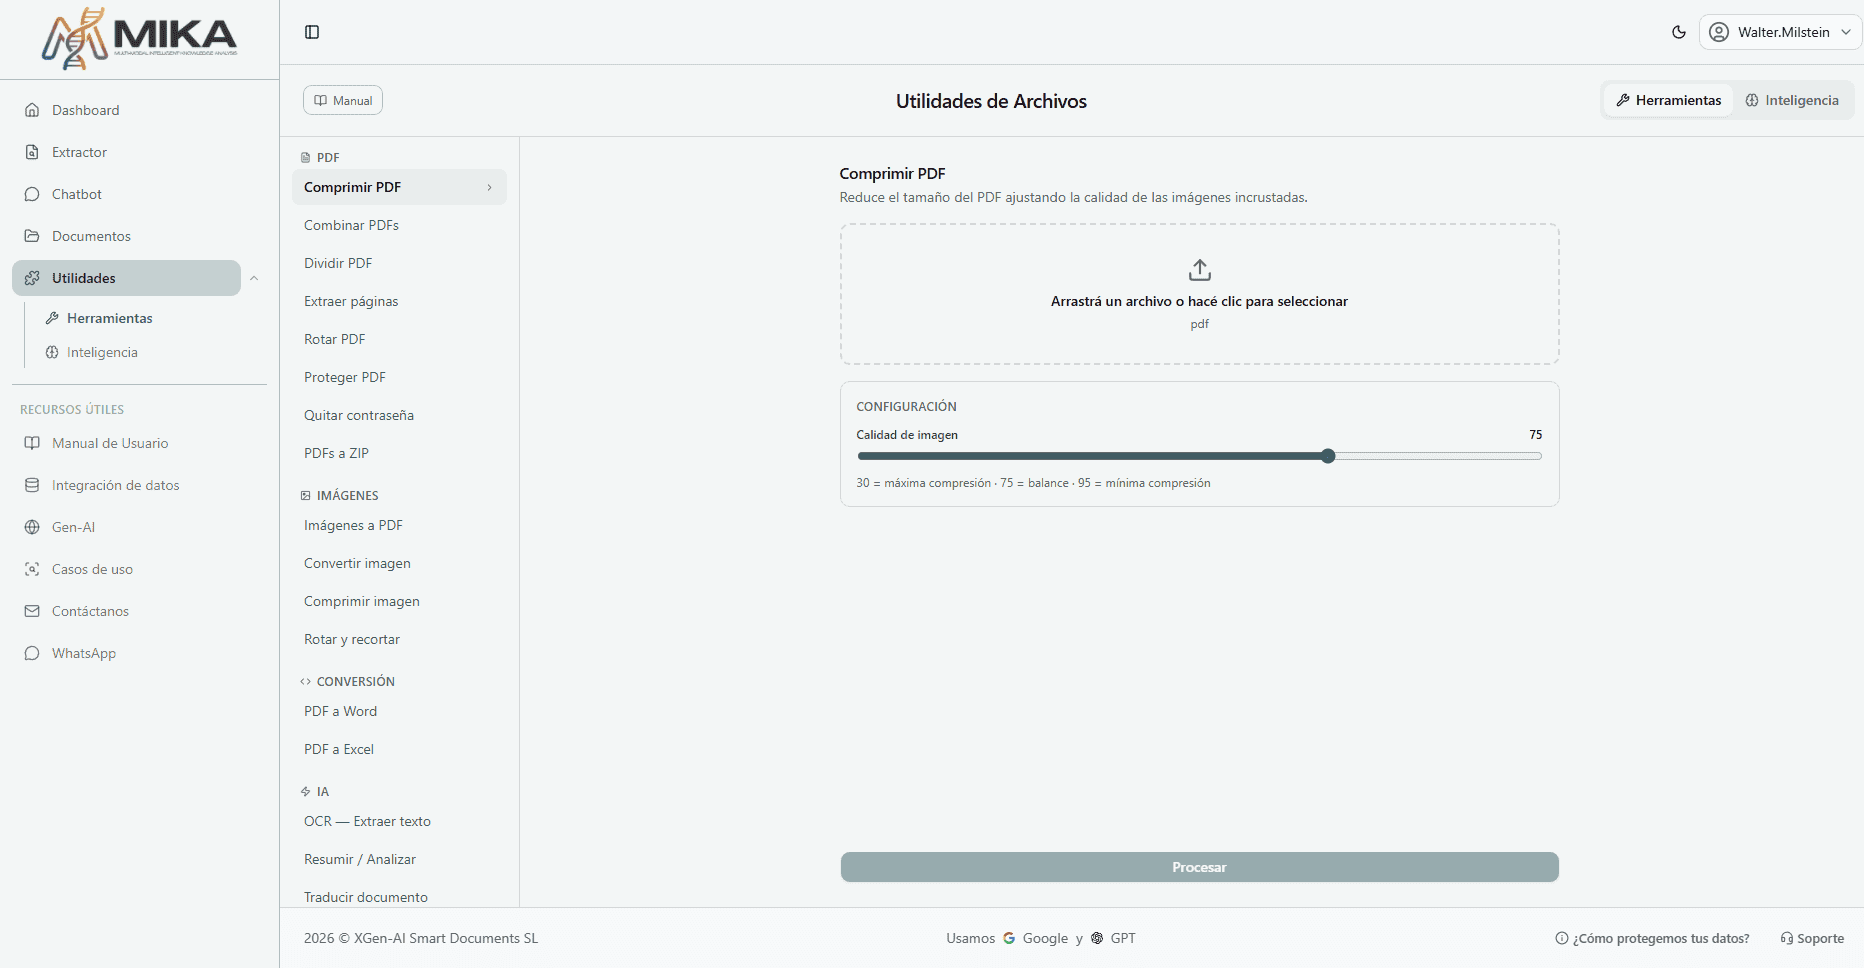
Tools for every document task
Beyond its core capabilities, MIKA includes 17 tools for manipulating PDFs, images, text and conversions — plus an intelligence module with semantic search and advanced reasoning.
- PDF operations — Compress, merge, split, protect, rotate and more.
- Image operations — Convert, compress, rotate and crop.
- Document conversion — PDF to Word, PDF to Excel and back.
- Text and analysis — OCR, summarization, translation and multi-step reasoning over documents.
One panel to manage your whole team in MIKA
MIKA includes its own administration panel for managing users, companies and usage — built around an access model designed for organizations, not individual users.
Activity log, filterable by company, user and level.
Superadmin
Global view: companies, users, products, licenses and logs across the whole system.
Company admin
Manages users and views metrics for their own organization.
User
Accesses their individual panel within MIKA.
From document to result, in a few steps.
- 01
Set up a template
Upload a sample document and choose the fields you want to extract.
- 02
Process in bulk
Upload a ZIP with many documents of the same type and let MIKA process them in parallel.
- 03
Review and export
Correct anything that needs it and export to CSV, Excel or JSON.
This is what MIKA looks like on the inside.
Browse real screenshots of the platform or watch the video tutorials.
Meet Mika
Explore all the features of our document intelligence platform

80+ languages and dialects supported
MIKA processes, extracts and converses in dozens of languages and regional variants from around the world.
+80
languages and dialects
Built for where information carries weight.
The following are illustrative examples of what MIKA can solve in each sector — not a client history.
Handwritten clinical records
How MIKA would solve it:
OCR of medical handwriting, diagnosis extraction and automatic pseudonymization.
Technology applied:
OCR + extraction + anonymization
Readmission prediction
How MIKA would solve it:
Analyzes patient history and estimates the probability of readmission.
Technology applied:
Predictive machine learning
Pharmacovigilance
How MIKA would solve it:
Processes adverse-event reports and groups patterns to generate alerts.
Technology applied:
Clustering + time series
Don't see your industry here?
MIKA adapts to different document types and processes. Tell us about your case and let's look at it together.
Generative AI without exposing your sensitive data.
Before any document reaches an AI model, whether MIKA's own or an external one, MIKA detects and tokenizes the sensitive data it contains: names, ID numbers, emails, phone numbers, banking data, health data and geolocation.
That information can only be reversed — restored to its original form — by authorized users. The rest of the system, including external AI models, never sees it.
MIKA is designed to facilitate compliance with GDPR, the EU AI Act, NIS2, DORA and Spain's LOPDGDD, and its infrastructure is aligned with ISO 27001, SOC 2 Type II and Spain's National Security Framework (ENS).
From document to decision, with no black boxes
Information comes in from your usual sources, flows through MIKA's three layers with automatic pseudonymization, and comes out as an answer, a structured data point, or an action.
Deploy it the way you need
MIKA can be deployed in the cloud, on-premise, or in a hybrid model, depending on your organization's requirements.
Most tools solve one piece. MIKA integrates all of them.
Most document AI solutions do one thing well: they extract, or they converse, or they automate. MIKA combines all three layers — generative AI, machine learning and Big Data — in a single platform, so you don't need to chain several tools together to get a result.
Multi-LLM, not a single vendor
Use GPT, Gemini, Claude or MIKA's own LLM depending on the case, without being locked into a single provider.
Native for Big Data
MIKA can integrate with Spark, Databricks and Kafka to scale to volumes a single language model can't process.
A broad machine learning catalog
20+ specialized models for prediction, classification and anomaly detection, chosen per case.
Pseudonymization from the first document
Sensitive data protection isn't an optional layer — it happens before any model sees the information.
Let's start by showing you MIKA with your own documents.
Schedule a demo and we'll show you how MIKA would process the kind of information your team works with every day.